FreqGS:
Frequency-Guided Gaussian Splatting for
High-Fidelity Novel View Synthesis from
Monocular Street Scenes

Ahmet Cagatay Seker1,2,     Sang Chul Ahn1,2,✉    
✉ Corresponding Author.
1 University of Science and Technology,
UST Logo
2 Korea Institute of Science and Technology,
KIST Logo

TL;DR: FreqGS improves monocular novel view synthesis by combining frequency-guided anchor initialization with error-voxel-based densification, producing sharper details and more complete street-scene reconstructions while improving robustness under lateral viewpoint extrapolation.


Sample Image.

FreqGS improves high-frequency detail reconstruction and produces more consistent renderings at extrapolated viewpoints in forward-moving monocular street scenes. On held-out views (top), our method better preserves lane markings and subtle road details, yielding improved regional metric performance. At extrapolated viewpoints (bottom), it preserves more coherent lane geometry and sharper road–sidewalk boundaries, whereas existing methods produce blurred, duplicated, or distorted structures.

Abstract

3D Gaussian Splatting (3DGS) enables real-time novel view synthesis with high visual quality. However, in forward-moving urban street scenes, existing methods often struggle to reconstruct fine structures and high-frequency details because sparse SfM initialization and local densification heuristics result in incomplete coverage and over-smoothed renderings. To address these limitations, we propose a novel method that jointly leverages region-aware frequency-guided initialization and error-voxel-based densification for high-fidelity monocular novel view synthesis. Our initialization performs frequency-guided pixel sampling within partitioned regions, improving fine-detail representation and coverage in low-texture areas. During training, our densification aggregates multi-view image-space color and frequency discrepancies into 3D error voxels, guiding the selective insertion of new anchors in persistently under-reconstructed regions. We further introduce a frequency-derived direction map as an auxiliary constraint to encourage structural consistency. Experiments on publicly available street-scene datasets demonstrate that our method outperforms existing 3DGS-based approaches, achieving superior rendering fidelity and fine-detail preservation on held-out views while generating more structurally consistent and visually accurate renderings under viewpoint extrapolation.

Method

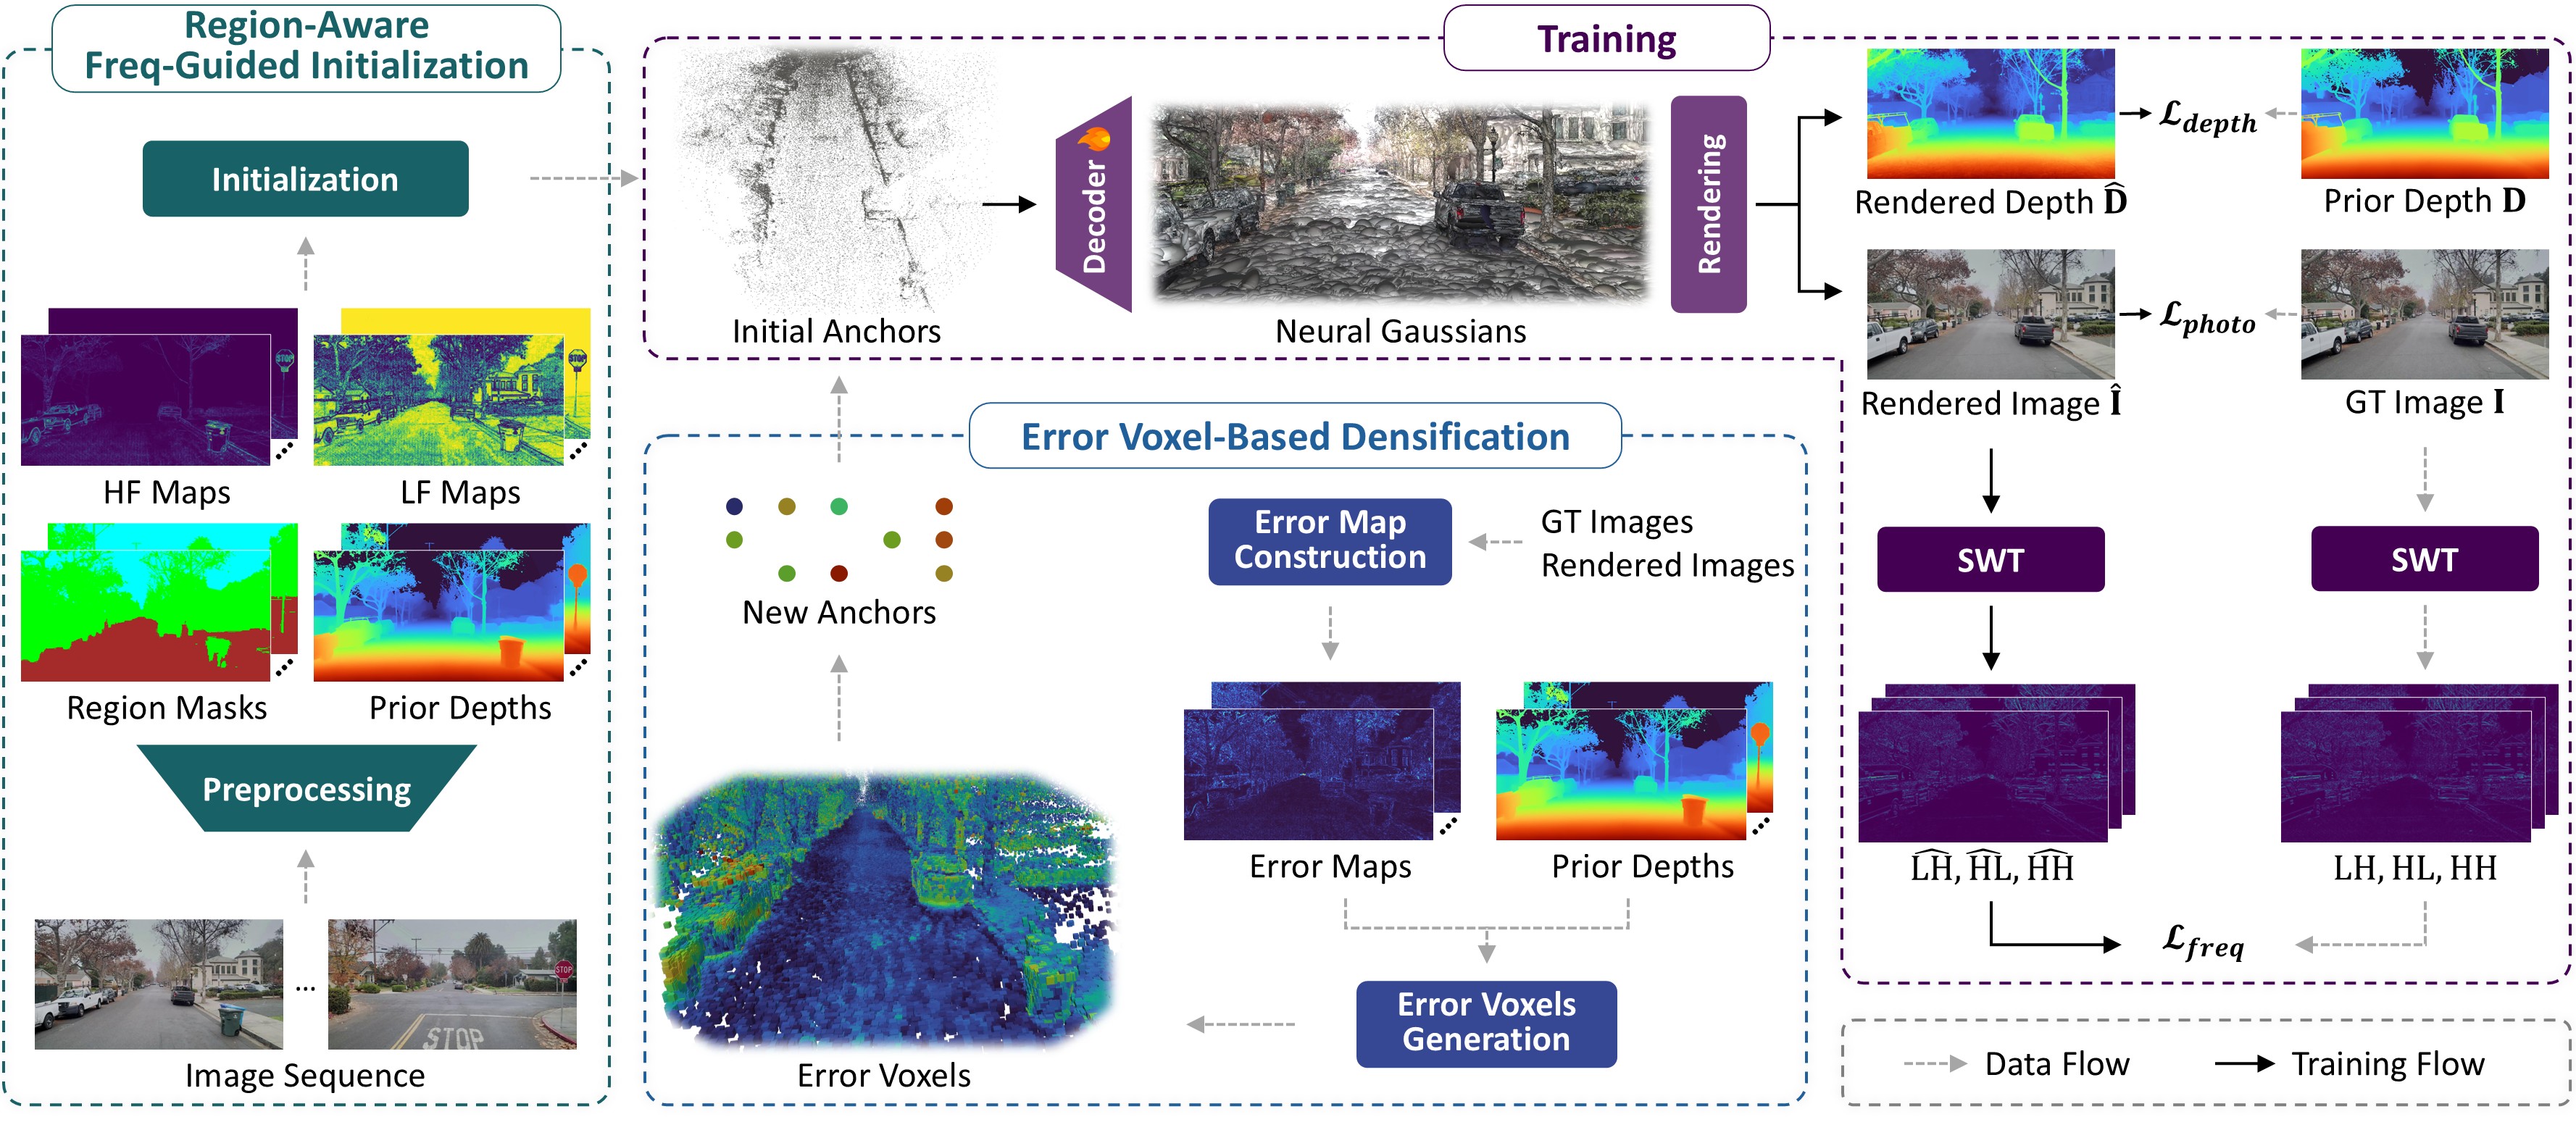
FreqGS takes a forward-moving monocular image sequence as input and reconstructs the scene using adaptive neural Gaussian anchors. It first initializes anchors with semantic, depth, and frequency guidance, then optimizes them using color, depth, and frequency-aware losses. During training, image-space errors are back-projected into a 3D error volume to insert new anchors in poorly reconstructed regions, improving fine-detail reconstruction.

Novel View Synthesis

Novel view synthesis results across diverse scenes. These videos present renderings along smoothly varying camera trajectories, demonstrating high visual quality, consistent scene geometry, and stable appearance across novel viewpoints.

Comparisons with Previous Methods

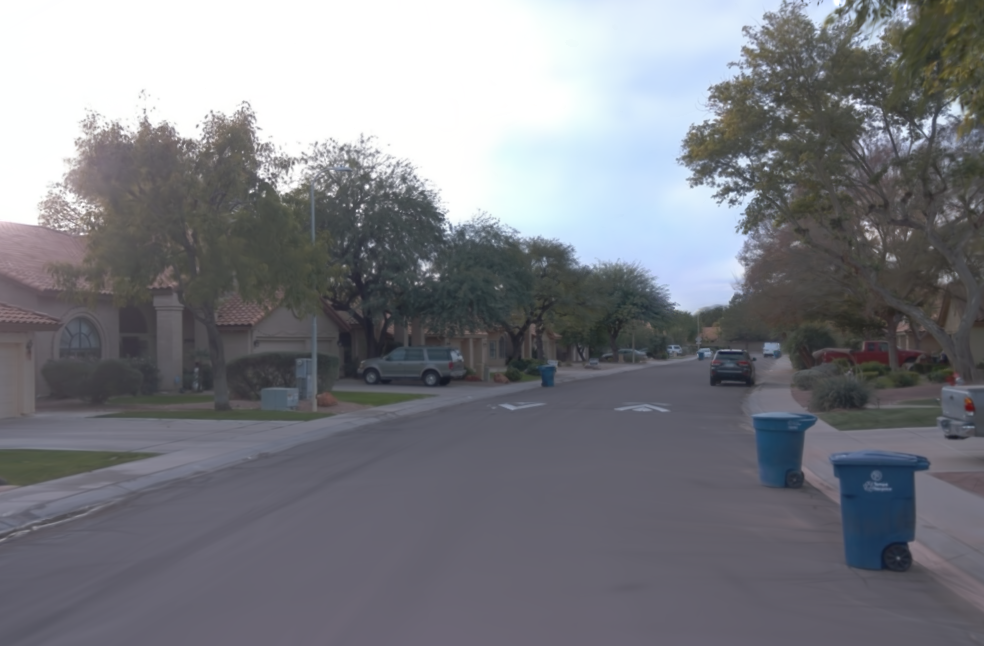
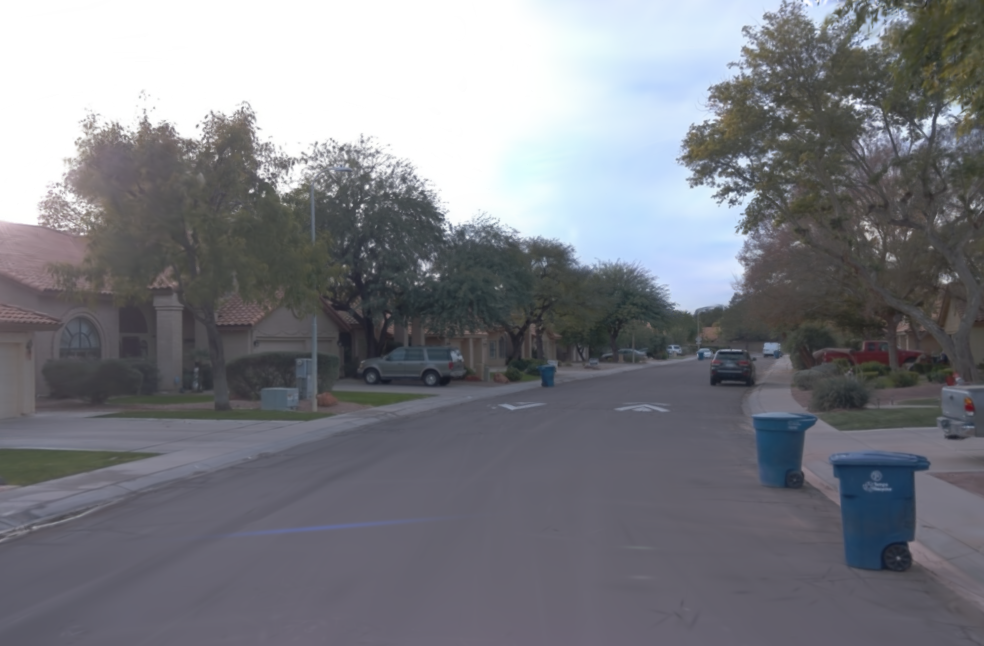
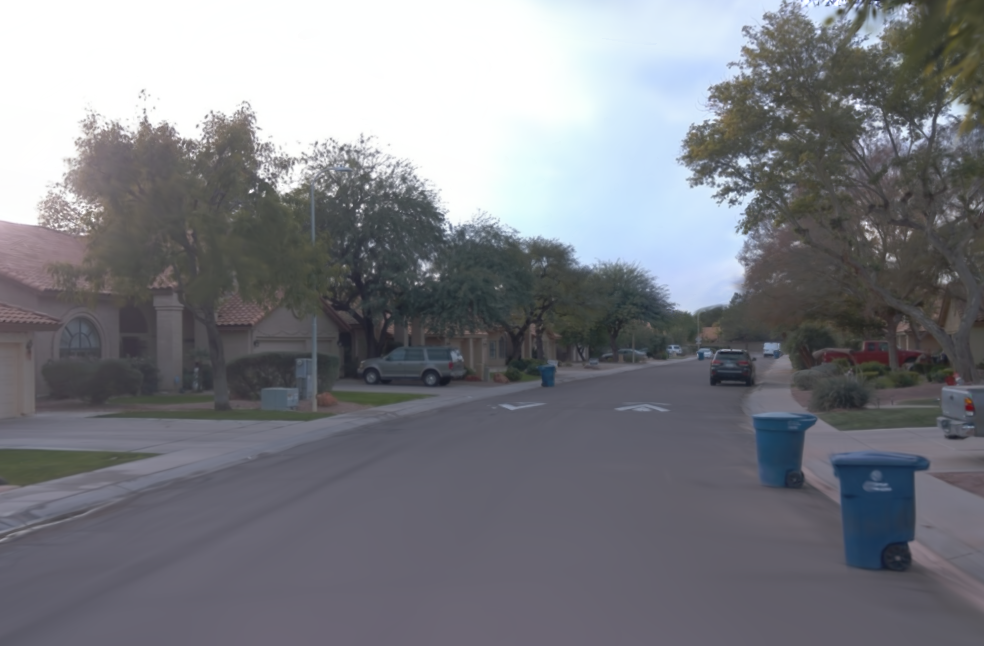
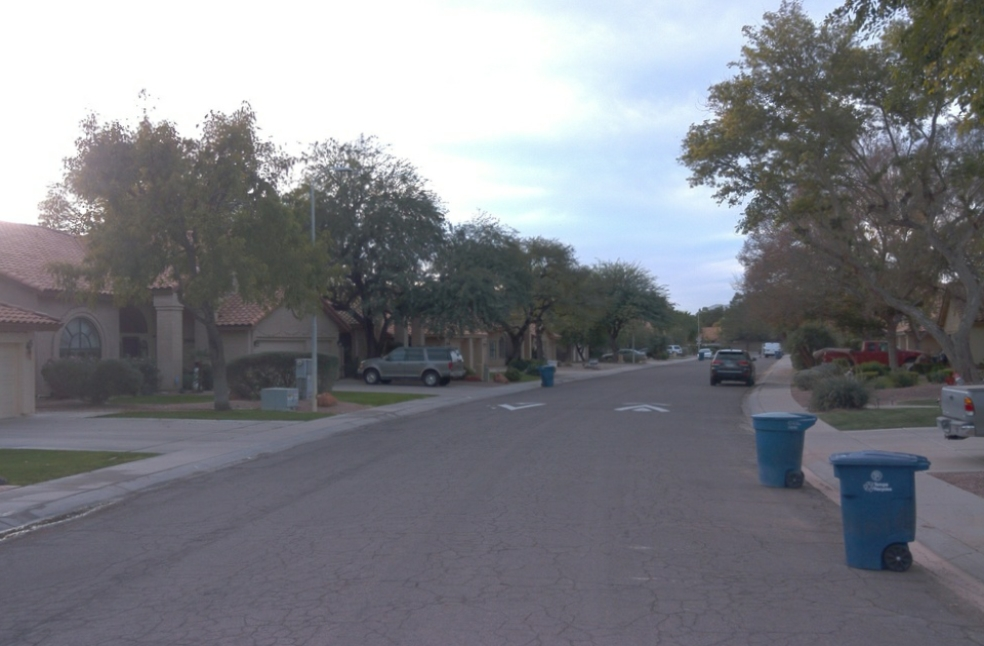
Qualitative comparison on held-out views. Compared with previous approaches, our method better preserves fine road structures and high-frequency details, producing sharper renderings with reduced blur artifacts.

Scene 1

Ours
3DGS
Ours
GaussianPro
Ours
GS-LPM
Ours
Scaffold-GS*
Ours
Pixel-GS
Ours
Ground Truth

Scene 2

Ours
3DGS
Ours
GaussianPro
Ours
GS-LPM
Ours
Scaffold-GS*
Ours
Pixel-GS
Ours
Ground Truth

Scene 3

Ours
3DGS
Ours
GaussianPro
Ours
GS-LPM
Ours
Scaffold-GS*
Ours
Pixel-GS
Ours
Ground Truth

Video Comparisons with Previous Methods

These videos compare novel-view renderings produced by our method and previous approaches along smoothly varying camera trajectories. Our method better preserves fine road structures and high-frequency details while maintaining more consistent geometry and appearance across viewpoints. Please refresh the page if you notice any synchronization or alignment issues between the video pairs.


Scene 1

Ours
3DGS
Ours
Scaffold-GS*
Ours
GaussianPro
Ours
Pixel-GS
Ours
GS-LPM


Scene 2

Ours
3DGS
Ours
Scaffold-GS*
Ours
GaussianPro
Ours
Pixel-GS
Ours
GS-LPM

Extrapolated View Comparison

Qualitative comparison under increasing viewpoint extrapolation. Rendering results are shown for the original test view and for mild, moderate, and strong lateral camera extrapolation.


Scene 1
As the camera moves farther from the training trajectory, the baseline methods increasingly produce blurred, duplicated, curved, or discontinuous lane markings and road boundaries. Our method preserves a more continuous lane boundary and maintains comparatively stable road structure in the rendered images under mild and moderate extrapolation, while showing fewer distortions under strong extrapolation. Nevertheless, all methods degrade under large viewpoint shifts because the extrapolated regions are only weakly constrained by the monocular training views. Please zoom in on the figure for a clearer visualization of the results.


Scene 2
The dashed boxes indicate selected sidewalk and road-boundary regions, and the corresponding enlarged views highlight local geometric distortions. As the camera moves farther from the observed trajectory, the baseline methods increasingly produce blurred or irregular curb and sidewalk structures. Our method preserves more continuous road boundaries and more coherent sidewalk geometry under mild and moderate extrapolation, while showing comparatively fewer distortions under strong extrapolation. However, all methods degrade under large viewpoint shifts because these regions are weakly constrained by the monocular training trajectory. Please zoom in on the figure for a clearer visualization of the results.
Extrapolated-View Video Comparisons

These videos show continuous lateral camera movement from the center of the road toward the roadside, enabling direct comparison of how each method degrades as the viewpoint moves farther from the observed camera trajectory. Our method maintains more stable road geometry, lane markings, and scene structure over a wider range of viewpoints, while the baselines exhibit earlier blurring, duplication, and geometric distortion.


These videos show renderings along a forward-moving camera trajectory from extrapolated viewpoints. Our method better preserves fine road structures, lane continuity, and geometric consistency while producing sharper and more stable renderings across viewpoints.

Initial Point Distribution


Initial anchor distribution for various scenes. Compared with sparse SfM initialization, our method produces a denser and more spatially balanced anchor distribution, improving coverage of textureless road surfaces and fine, high-frequency structures.

BibTeX

If you find this work useful in your research, please consider citing:

@article{seker2027freqgs,
  title     = {FreqGS: Frequency-Guided Gaussian Splatting for High-Fidelity Novel View Synthesis from Monocular Street Scenes},
  author    = {Seker, Ahmet Cagatay and Ahn, Sang Chul},
  journal   = {},
  volume    = {},
  pages     = {},
  year      = {},
  publisher = {}
}